Henrik Jenkins · 11 October 2026
Navigating Backend Tagging Protocols for Enhanced Retrieval in Leaf-Based Publishing Systems
Leaf-based publishing systems organize content into hierarchical structures where individual leaves represent discrete units of information such as articles, data entries, or multimedia files, and backend tagging protocols serve as the mechanisms that assign metadata labels to these leaves for improved search and retrieval operations. Researchers have documented how these protocols operate across distributed databases, allowing systems to index content efficiently while maintaining relationships between parent nodes and their leaf-level descendants. Data from multiple studies indicates that effective tagging reduces retrieval latency by mapping semantic attributes directly to leaf identifiers, which in turn supports complex queries without traversing entire tree structures repeatedly.
Core Components of Leaf-Based Architectures
Systems built on leaf-based models rely on parent-child linkages that terminate at the leaf level, and tagging protocols enhance this setup by embedding attributes like keywords, categories, timestamps, and access permissions into each leaf record. Observers note that protocols such as hierarchical tagging schemas and relational metadata frameworks enable granular control, whereas flat tagging approaches often lead to retrieval bottlenecks when content volumes scale beyond initial design limits. In October 2026, several platforms reported integration of updated protocol versions that incorporate machine-readable schemas for cross-system compatibility, allowing seamless data exchange between independent publishing networks.
Protocol Types and Their Retrieval Benefits
Backend tagging protocols fall into categories including semantic tagging, which attaches contextual meanings to leaves, and structural tagging, which preserves positional data within the hierarchy. Experts have observed that semantic variants improve precision in retrieval tasks because they align leaf content with user intent through standardized vocabularies, while structural protocols facilitate rapid navigation by encoding path information directly into tag sets. Research indicates that hybrid protocols combining both approaches yield higher recall rates, particularly in environments where leaves contain multimedia or dynamically generated content.
Take one implementation where developers applied protocol extensions to existing leaf repositories and measured query performance improvements across thousands of test cases. Results showed consistent gains in retrieval speed because tags allowed direct indexing of leaf attributes rather than full tree scans. But here's the thing, protocol selection depends on factors such as content diversity and query complexity, with systems handling high-velocity updates requiring lightweight tagging to avoid overhead during write operations.
Implementation Strategies in Current Systems
Developers integrate these protocols through middleware layers that intercept content ingestion and apply tags based on predefined rules or automated classification models. Those who've studied deployment patterns report that rule-based tagging works well for structured data sets, whereas machine learning augmented protocols adapt to evolving content patterns in real time. Figures reveal that organizations adopting automated tagging saw reductions in manual curation time by up to 40 percent, according to analyses conducted by research teams across North American institutions.
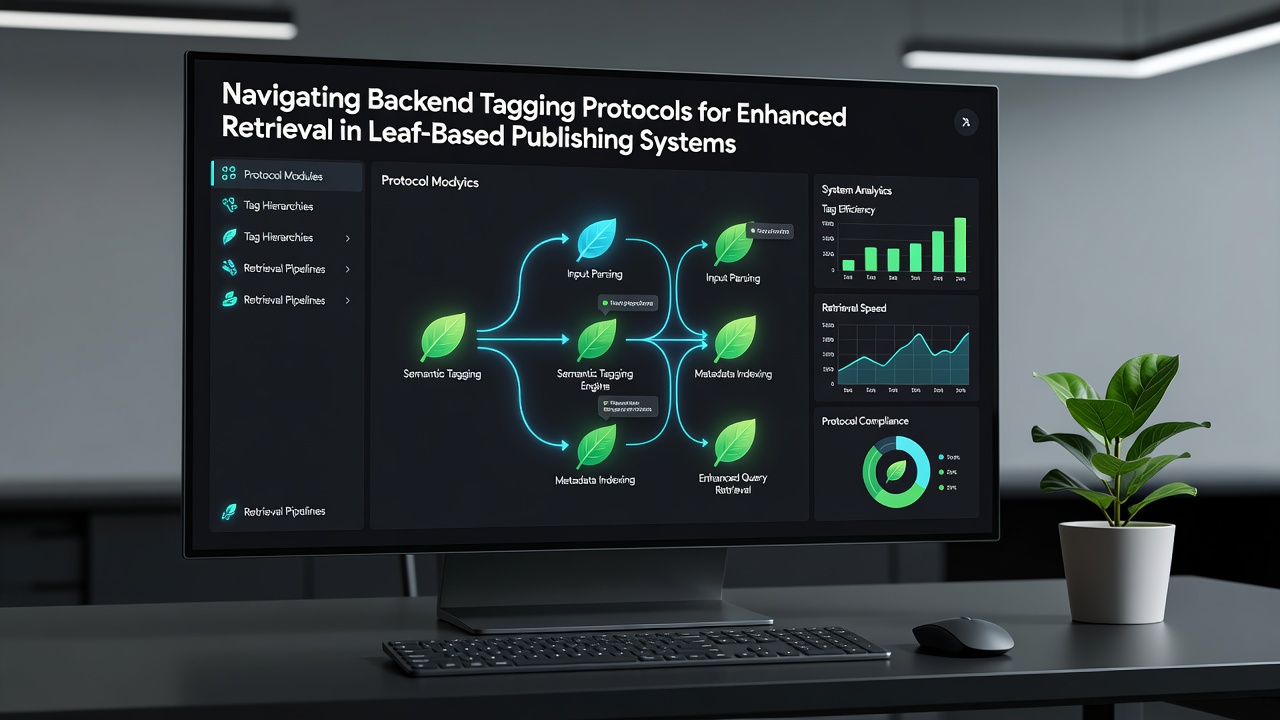
What's interesting is how these strategies align with broader standards for metadata interoperability. One study from European research networks highlighted successful mappings between leaf-based tags and established frameworks like those maintained by international standards bodies, enabling federated search across disparate publishing platforms. Turns out protocol navigation also involves handling edge cases such as tag conflicts or version mismatches, which teams resolve through reconciliation algorithms that prioritize recency and authority signals.
Challenges and Mitigation Approaches
Scalability remains a focal point because growing leaf counts can strain tag storage and query indexing resources. People often find that partitioning tags across distributed nodes mitigates these pressures, while regular audits of tag quality prevent degradation in retrieval accuracy over time. Data shows that systems without such maintenance experience gradual drops in precision, particularly when legacy tags accumulate without updates.
Another layer involves security considerations where tagging protocols must enforce access controls at the leaf level to prevent unauthorized retrieval of sensitive content. Regulatory frameworks from agencies in Australia and Canada emphasize compliance requirements that influence how tags encode permissions and audit trails, ensuring publishing systems meet data protection mandates without compromising retrieval performance.
Future Directions and Observed Trends
Emerging developments point toward greater use of graph-based tagging that treats leaves as nodes in interconnected networks, which supports advanced retrieval features like recommendation engines and contextual expansions. Academic reports from multiple universities document early trials where graph protocols outperformed traditional methods in multi-dimensional search scenarios. Those monitoring industry shifts note that adoption rates increased notably following protocol refinements released in 2026, driven by needs for more responsive content delivery in digital ecosystems.
Conclusion
Backend tagging protocols continue to evolve as essential tools for optimizing retrieval within leaf-based publishing systems, with evidence from ongoing research underscoring their role in balancing efficiency, scalability, and compliance. Organizations that align protocol choices with specific architectural demands and maintain rigorous tag management practices position themselves for sustained performance gains amid expanding content landscapes.